Audio
9 stories in this blend
 The Neuron·1d ago
Whistle
Whistle is a lightweight speech recognition tool that converts audio into text entirely on local device hardware. It runs efficiently on standard computer processors without requiring external cloud servers or specialized graphics hardware. The application works well for privacy conscious users needing offline transcription.
 The Neuron·6d ago
Suno Speech
An audio generation tool that outputs spoken voice overs alongside an original background music track. It is designed for creators who need custom sound scores matched to spoken narration.
 Superhuman·6d ago
Sudo Offline Audio Player
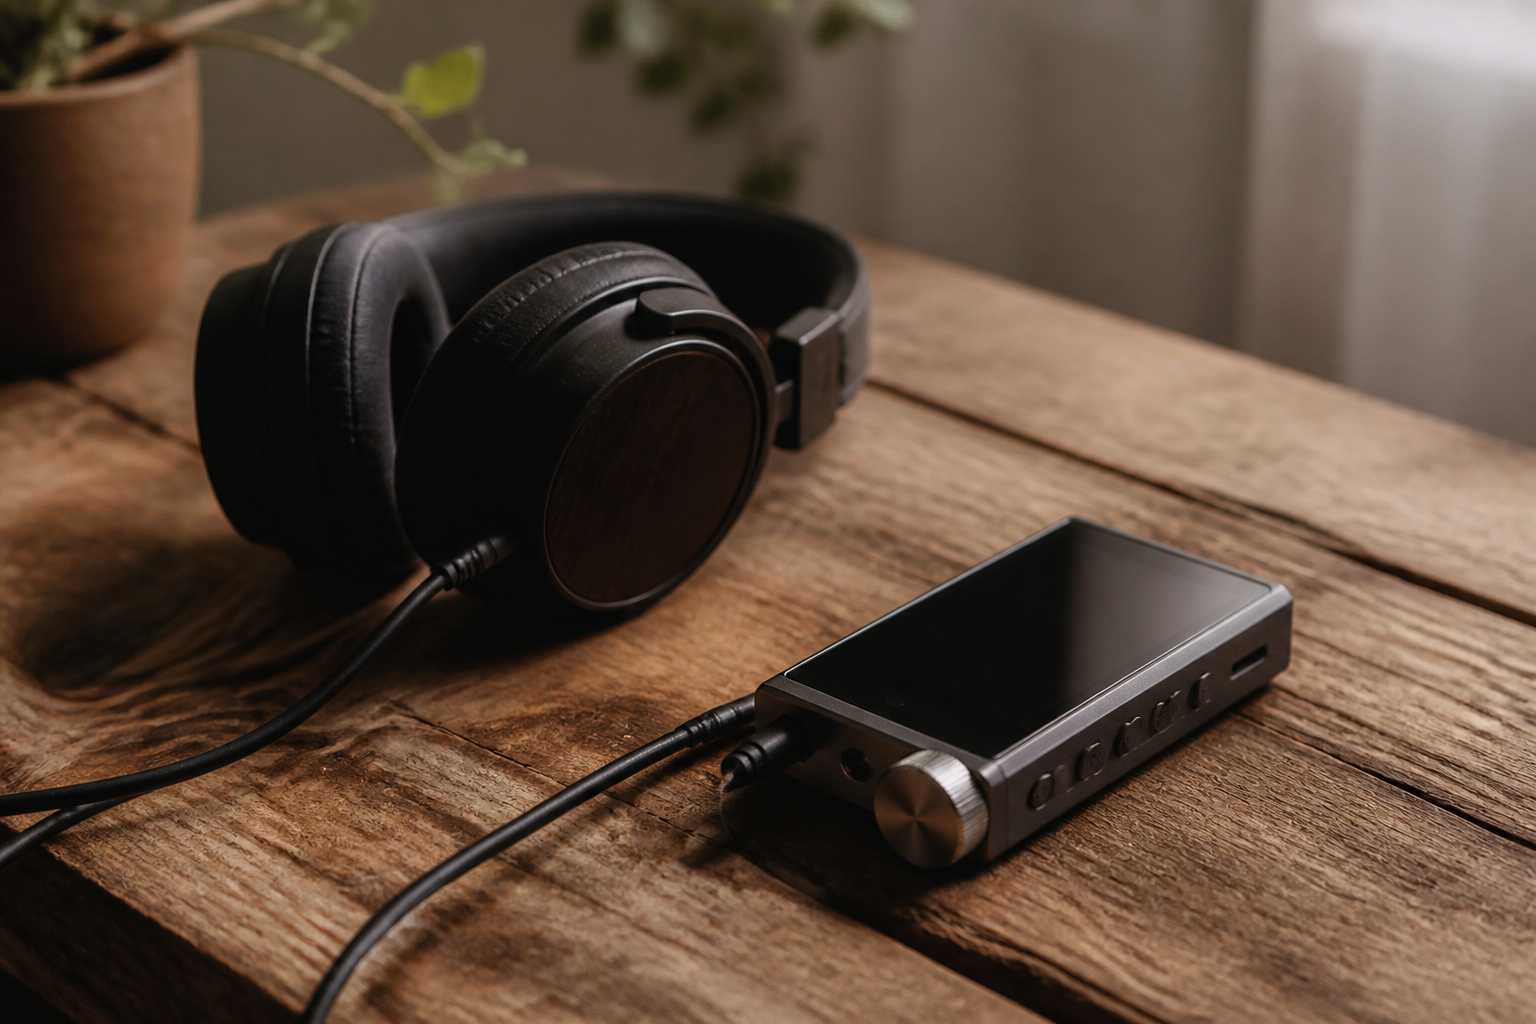
Sudo is a dedicated mobile audio gadget designed exclusively for listening to stored music files using tactile physical controls. It suits users looking for a distraction free music device without phone notifications or streaming connectivity.
 The Neuron·Sep 29
Eleven v4 delivers realistic multi speaker voice generation across languages
An advanced voice generation engine supporting expressive dialogue and real time adjustments across dozens of global languages. It fits audio producers, game developers, and translators building interactive voice experiences.
 There's An AI For That·Sep 23
Linden by Speechmatics
Linden is an audio transcription and voice tool that accurately captures complex contact information such as names and postal codes while identifying different speakers on calls.
 There's An AI For That·Sep 12
Yinso
A musical generation application that builds complete vocal tracks across multiple musical genres based on written descriptions and mood themes. Users can view lyrics, download generated audio files, and organize their song collections.
 There's An AI For That·Sep 9
Reline
Reline records phone calls and classroom lectures directly on your mobile device to generate structured meeting notes. Users can ask questions about recorded audio and receive answers linked directly to precise audio timestamps.
 There's An AI For That·Sep 6
VoiceStudio
VoiceStudio provides open-source voice cloning, video dubbing, and audiobook narration tools that run locally without account registration. It suits media producers and multilingual creators wanting offline voice synthesis across hundreds of languages.
 There's An AI For That·Aug 23
Open-source voice cloning tool translates speech into 14 languages
An open-source voice synthesis project called Confucius4-TTS can replicate a speaker's voice using a single audio sample. The system generates speech in 14 different languages while removing native accents and retaining natural emotional tone.


